Published · journal article
Automatic text‐to‐gesture rule generation for embodied conversational agents
2020 · Computer Animation and Virtual Worlds
First author
Automatically mined rules reduce manual co-speech gesture authoring.
From the paper
Author abstract
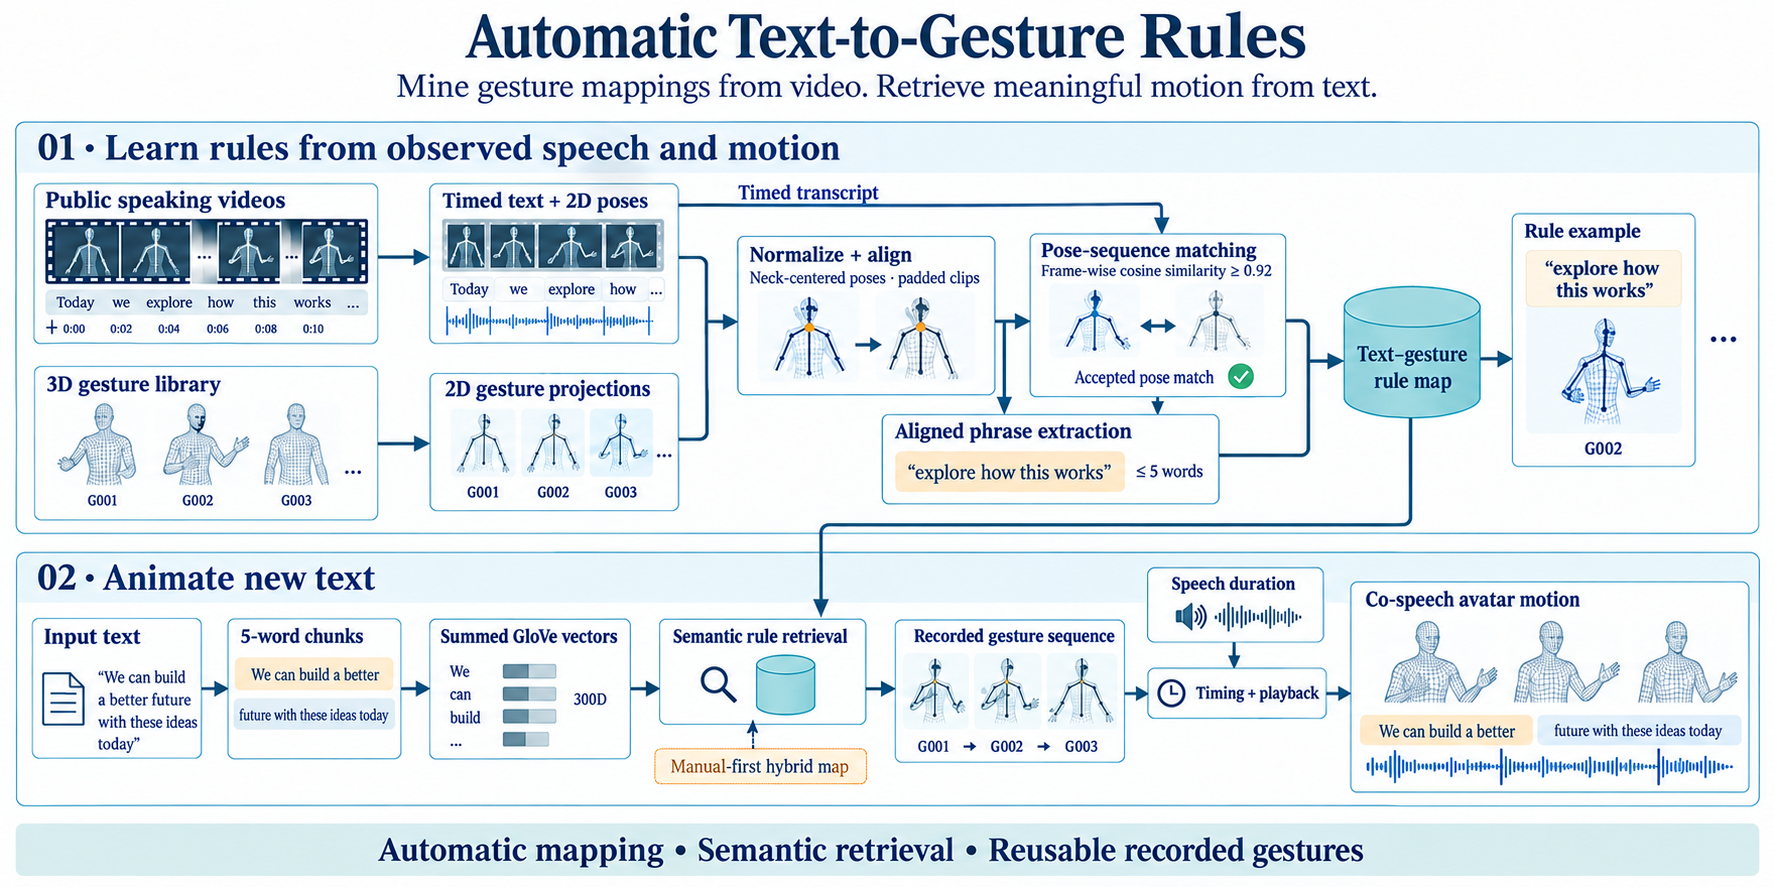
Interactions with embodied conversational agents (ECAs) can be enhanced using humanlike co-speech gestures. Traditionally rulebased co-speech gesture mapping has been utilized for this purpose. However, the creation of this mapping is laborious and often requires human experts. Moreover, human-created mapping tends to be limited, therefore prone to generate repeated gestures. In this paper, we present an approach to automate the generation of rule-based co-speech gesture mapping from publicly available large video dataset without the intervention of human experts. At runtime, word embedding is utilized for rule searching to get the semantic-aware, meaningful, and accurate rule. The evaluation indicated that our method achieved comparable performance with the manual map generated by human experts, with a more variety of gestures activated. Moreover, synergy effects were observed in users’ perception of generated co-speech gestures when combined with the manual map.
Author-written abstract from the author manuscript.
In plain language
What this work does
The method mines text-to-gesture mappings from public video rather than requiring experts to author every rule. At runtime, word embeddings search for semantically relevant rules and activate recorded gesture units. User evaluation compares mined maps with manual maps and their combination.
- 01Public video + pose
- 02Automatic rule mining
- 03Semantic gesture retrieval
At a glance
Method, evidence, and scope
| Input | Offline video and pose; runtime text |
|---|---|
| Output | Retrieved co-speech gestures |
| Method | Automated video-to-rule mapping with semantic word-embedding search |
| Data and scope | Approximately 106 hours of public video |
| Evaluation | Comparison with manual rule maps; gesture variety and user perception |
| Limitations | Rule retrieval depends on corpus coverage and the gesture inventory; automatic mapping does not directly decode novel motion. |
Watch the system
Paper presentation / demo
Implementation and artifacts
Code and setup
Independent implementation of the paper’s core ideas, with setup instructions and data preparation documented in the repository README. The institute’s original source, datasets and trained models are not distributed.
Browse code and setup guideReference this work
Citation
Ghazanfar Ali, Myungho Lee, Jae‐In Hwang. Automatic text‐to‐gesture rule generation for embodied conversational agents. Computer Animation and Virtual Worlds, 2020. Volume 31. Issue 4-5. Article e1944. DOI: 10.1002/cav.1944.
@article{automatictexttogesture2020,
  title = {{Automatic text‐to‐gesture rule generation for embodied conversational agents}},
  author = {Ali, Ghazanfar and Lee, Myungho and Hwang, Jae‐In},
  year = {2020},
  journal = {Computer Animation and Virtual Worlds},
  volume = {31},
  number = {4-5},
  eid = {e1944},
  doi = {10.1002/cav.1944},
  url = {https://ghazanfarali.com/research/automatic-text-to-gesture/}
}