Published · poster
Improving Co-speech gesture rule-map generation via wild pose matching with gesture units.
2022 · SIGGRAPH Asia Posters
First author
Contrastive matching turns noisy video poses into a richer gesture rule map.
From the paper
Author abstract
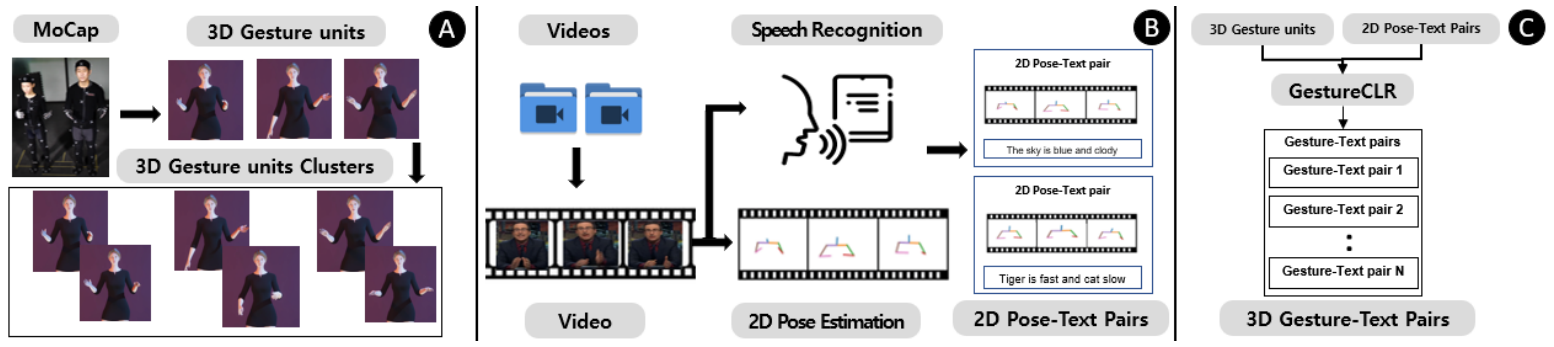
In this poster, we present a method to generate co-speech textto-gesture mapping for 3D digital humans. We obtained text and 2D pose data from public monologue videos. Gesture units were obtained from motion capture sequences. The method works by matching 2D poses to 3D gesture units. We trained a model via contrastive learning to improve the matching of noisy pose sequences with gesture units. To ensure diverse gesture sequences at runtime, gesture units were clustered using K-Mean clustering. We incorporated 2035 gestures and 210k rules. Our method is highly adaptable and easy to control and use. Demo Video : https://youtu.be/QBtGdGE1Wgk
Author-written abstract from the author manuscript.
In plain language
What this work does
The poster aligns 2D poses from public monologue videos with gesture units extracted from 3D motion capture. GestureCLR learns robust matching; K-Means clusters the units to support variety when retrieving gestures at runtime.
- 01Text + noisy video pose
- 02GestureCLR matching
- 03Clustered gesture rules
At a glance
Method, evidence, and scope
| Input | Video-derived text and 2D pose; captured 3D motion |
|---|---|
| Output | Text-to-gesture rules and clustered gesture units |
| Method | Contrastive pose-to-unit matching and K-Means clustering |
| Data and scope | 2,035 gesture units and 210,000 rules |
| Evaluation | Poster demonstrates the expanded gesture library and mapping pipeline |
| Limitations | This is a two-page poster; the later multilingual paper contains a separate user study and should be cited for that evidence. |
Watch the system
Paper presentation / demo
Implementation and artifacts
Code and setup
Independent implementation of the paper’s core ideas, with setup instructions and data preparation documented in the repository README. The institute’s original source, datasets and trained models are not distributed.
Browse code and setup guideReference this work
Citation
Ghazanfar Ali, Jae-In Hwang. Improving Co-speech gesture rule-map generation via wild pose matching with gesture units.. SIGGRAPH Asia Posters, 2022. Pages 1-2. DOI: 10.1145/3550082.3564185.
@inproceedings{wildposematching2022,
  title = {{Improving Co-speech gesture rule-map generation via wild pose matching with gesture units.}},
  author = {Ali, Ghazanfar and Hwang, Jae-In},
  year = {2022},
  booktitle = {SIGGRAPH Asia Posters},
  pages = {1-2},
  doi = {10.1145/3550082.3564185},
  url = {https://ghazanfarali.com/research/wild-pose-matching/}
}