Published · conference paper
Design of Seamless Multi-modal Interaction Framework for Intelligent Virtual Agents in Wearable Mixed Reality Environment
2019 · CASA
First author
A modular virtual guide combines speech, gaze, and spatial context in wearable MR.
From the paper
Author abstract
In this paper, we present the design of a multimodal interaction framework for intelligent virtual agents in wearable mixed reality environments, especially for interactive applications at museums, botanical gardens, and similar places. These places need engaging and no-repetitive digital content delivery to maximize user involvement. An intelligent virtual agent is a promising mode for both purposes. Premises of framework is wearable mixed reality provided by MR devices supporting spatial mapping. We envisioned a seamless interaction framework by integrating potential features of spatial mapping, virtual character animations, speech recognition, gazing, domain-specific chatbot and object recognition to enhance virtual experiences and communication between users and virtual agents. By applying a modular approach and deploying computationally intensive modules on cloud-platform, we achieved a seamless virtual experience in a device with limited resources. Human-like gaze and speech interaction with a virtual agent made it more interactive. Automated mapping of body animations with the content of a speech made it more engaging. In our tests, the virtual agents responded within 2-4 seconds after the user query. The strength of the framework is flexibility and adaptability. It can be adapted to any wearable MR device supporting spatial mapping.
Author-written abstract from the author manuscript.
In plain language
What this work does
The framework integrates spatial mapping, speech recognition, gaze, object recognition, a domain-specific chatbot, and virtual-character animation. Computationally intensive components run on a cloud platform to support a wearable device with limited resources.
- 01Speech + gaze + scene
- 02Modular agent / cloud
- 03Embodied MR response
At a glance
Method, evidence, and scope
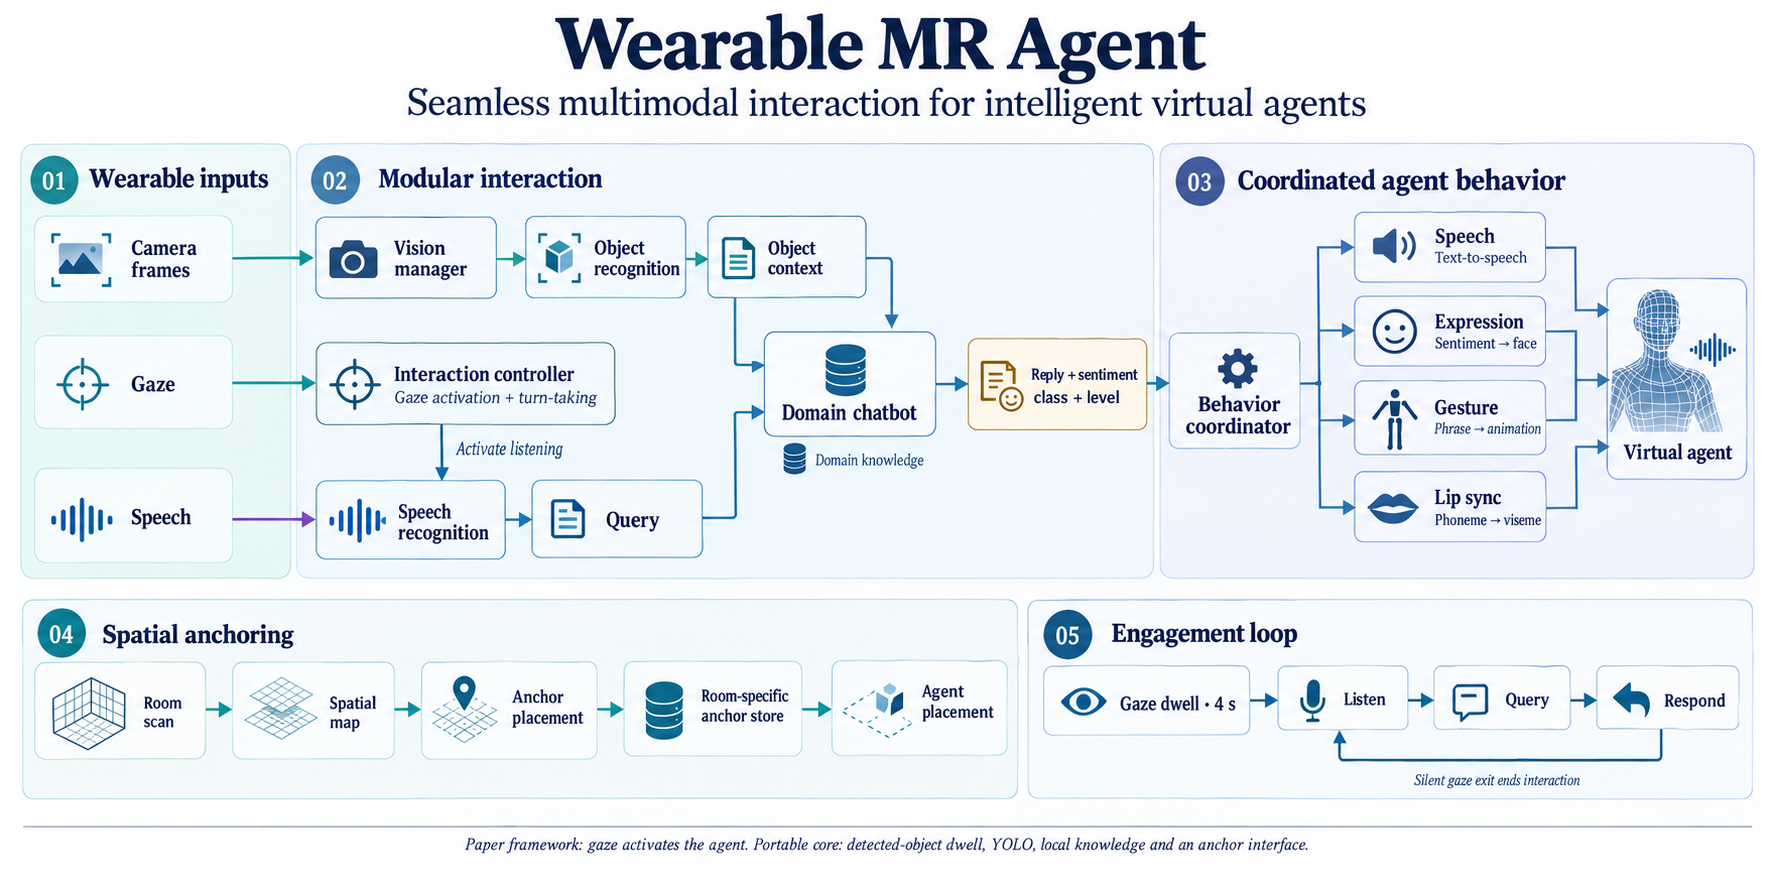
| Input | Speech, gaze, recognized objects, and spatial mapping |
|---|---|
| Output | An interactive virtual guide with verbal and animated responses |
| Method | Modular interaction framework with cloud-assisted processing |
| Data and scope | Wearable mixed-reality application scenarios |
| Evaluation | Paper reports responses within 2–4 seconds in its tests |
| Limitations | The response measurements describe the tested hardware, network, and scenarios; cloud connectivity and spatial mapping are required by the design. |
Watch the system
Paper presentation / demo
Implementation and artifacts
Code and setup
Independent implementation of the paper’s core ideas, with setup instructions and data preparation documented in the repository README. The institute’s original source, datasets and trained models are not distributed.
Browse code and setup guideReference this work
Citation
Ghazanfar Ali, Hong-Quan Le, Junho Kim, Seung-Won Hwang, Jae-In Hwang. Design of Seamless Multi-modal Interaction Framework for Intelligent Virtual Agents in Wearable Mixed Reality Environment. CASA, 2019. Pages 47-52. DOI: 10.1145/3328756.3328758.
@inproceedings{wearablemragent2019,
  title = {{Design of Seamless Multi-modal Interaction Framework for Intelligent Virtual Agents in Wearable Mixed Reality Environment}},
  author = {Ali, Ghazanfar and Le, Hong-Quan and Kim, Junho and Hwang, Seung-Won and Hwang, Jae-In},
  year = {2019},
  booktitle = {CASA},
  pages = {47-52},
  doi = {10.1145/3328756.3328758},
  url = {https://ghazanfarali.com/research/wearable-mr-agent/}
}